How do I track which marketing assets are actually being used?
Short answer: Not from your DAM. Downloads are not usage. To find what is actually running, work backwards from the live channels, identify every asset published across paid, organic, retail and influencer, then fingerprint each one back to its master. Filename matching fails, because markets recut and rename everything. This is asset utilisation tracking.
Why your DAM cannot answer this
Your DAM knows an asset exists, who uploaded it, what version is approved and how many times it was downloaded, but its knowledge ends at the moment someone clicks download. After that the file goes to an agency, a media buyer or a market team, and nothing in the system records what happened next. It cannot tell you whether the asset ran, on which channels, in which countries, for how long or behind how much spend, because none of that information ever travels back.
Download counts get used as a proxy for this constantly, and they fail in both directions rather than consistently in one, which is what makes them dangerous. Assets get downloaded fifty times and never run, while others run in twelve markets from a single download that got forwarded round on email. Several DAM vendors have added analytics modules that appear to address this, but read the documentation carefully before relying on one: most measure activity inside the DAM, meaning searches, downloads, internal engagement and portal traffic. That tells you how your team uses the library, which is a genuinely useful thing to know and an entirely different question from whether the work reached an audience.
What “used” should actually mean
Before you measure anything, define the term, because vague definitions are why these exercises produce numbers nobody trusts. A workable definition has four parts:
- Live. The asset appeared on a real consumer-facing channel, not a review link or an internal deck.
- Located. You know which market and which channel.
- Durable. You know the flight dates, because a two-day test and a nine-month always-on placement are not the same event.
- Attributable. You can trace it back to a specific master in the library.
Anything short of all four gives you a number you cannot act on, which is the reason so many utilisation exercises end in a slide nobody references again. “This asset was used” is not a finding, because it supports no decision. “This asset ran in four of eleven markets, on Meta only, for an average of nine days, from the Q2 master” tells you which markets to talk to, which channel was left untested, and whether the flight was long enough for the result to mean anything.
Where the data actually lives
The information exists. It is just scattered across systems that do not talk to each other, described in incompatible ways.
| Source | What it knows | What it misses |
|---|---|---|
| DAM | The master file, version, approval status, rights metadata | Anything that happened after download |
| Ad platforms (Meta, Google, TikTok, LinkedIn) | Creative that ran with spend behind it, impressions, results | Organic, retail, influencer. Creative IDs do not map to your filenames |
| Social management tools | Organic posts on owned handles | Paid, dark posts, creator-side content |
| Agency reporting | What the agency chose to report | Everything the agency did not think to mention |
The obvious move is to join these sources on filename or asset ID, and it fails almost immediately, because the asset that reaches a live channel is rarely the asset that left your library. Understanding why is the whole problem.
The recut problem
Local markets and agencies do not run your master, they run a version of it, and the difference is what breaks every attempt to measure this from a spreadsheet. A sixty-second hero film becomes a fifteen-second cutdown, a six-second bumper, a nine-by-sixteen vertical with burned-in local subtitles, a square version with a different end frame, and four static key visuals lifted from it, each renamed to whatever the person exporting it felt like typing.
None of those derivatives match the master on filename, file size, duration, resolution or embedded metadata, and every ad platform assigns its own creative ID with no relationship to yours. By the time your creative reaches a live channel the thread back to the library has been cut, and no amount of spreadsheet work restores it reliably, which is why teams who attempt this manually can usually recognise their own assets on sight but cannot automate a single step of it.
Solving that requires content fingerprinting, meaning identification based on what is actually inside the file, its visual and audio signature, rather than on what it happens to be called. This is the reason the problem stayed unsolved for so long: it presents as a reporting problem, and reporting tools cannot fix it, because underneath it is a recognition problem.
How to do it manually
You can get a defensible answer without software. It is slow, and it is a sample rather than a census, but it is real and it is the right first step before buying anything.
- Pick a bounded scope. One campaign, one quarter, five to eight markets. Do not attempt the whole library.
- List the masters. Every asset shipped for that campaign, from the DAM.
- Pull live inventory per market. Meta Ad Library, TikTok Creative Center and the platforms’ own ad transparency tools show currently running ads for any advertiser. Add organic from each market handle, plus whatever retail and influencer activity you can get sight of.
- Match by eye. A person who knows the campaign watches the live creative and identifies which master it derived from. This is the slow part and it cannot be delegated to someone unfamiliar with the work.
- Record the four attributes. Live, located, durable, attributable.
- Calculate two numbers. Utilisation rate: masters that ran at least once, as a share of masters produced. Depth: average number of markets per used master.
Budget two to three days for a competent person on a single campaign across a handful of markets. Do it once and you will have a genuinely useful number and a very clear sense of why nobody does it every quarter.
When manual stops working
The threshold is lower than people expect. Manual audit breaks when any of these are true:
- More than about ten markets, because the matching effort scales linearly and the sampling error grows
- Always-on content rather than discrete campaigns, because there is no natural point to audit
- Meaningful influencer or retail partner activity, because it is not in any system you control
- A requirement to report quarterly, because a three-day audit per campaign per quarter is a full-time job nobody has
- Rights or licensing exposure attached to the answer, because a sample is not adequate when the question is compliance
If you are auditing to satisfy curiosity, manual is fine. If you are auditing because production budget is being questioned or because legal wants assurance, a sample will not survive scrutiny.
What to automate this properly requires
Four capabilities separate a tool that answers the question from a tool that produces a dashboard, and each is worth turning into a demo request rather than taking on trust.
The first is coverage beyond paid media. Most platforms claiming asset tracking read from ad platform APIs, which means paid only, so if your organic, retail partner and influencer activity is not covered then you are measuring the part of the problem you could already see. The second is fingerprinting rather than metadata matching, and it is the one that fails most often in practice. Ask to see a fifteen-second local cutdown, redubbed and renamed, traced back to its sixty-second master. If the matching runs on filenames or embedded metadata it will return close to nothing on real enterprise creative, and no vendor is going to volunteer that unprompted.
The third is historical coverage. A tool that reports what is live today cannot tell you what ran for nine days in March, and because utilisation is a duration question rather than a snapshot, the archive matters as much as the current state. The fourth is a route back to your own library, since usage data that does not connect to a DAM record produces a report nobody can act on. The join between live asset and approved master is the entire point of the exercise.
Ask for implementation timelines in writing as well. The range across this category runs from days to several months and it is rarely on the pricing page.
How Medialake does it
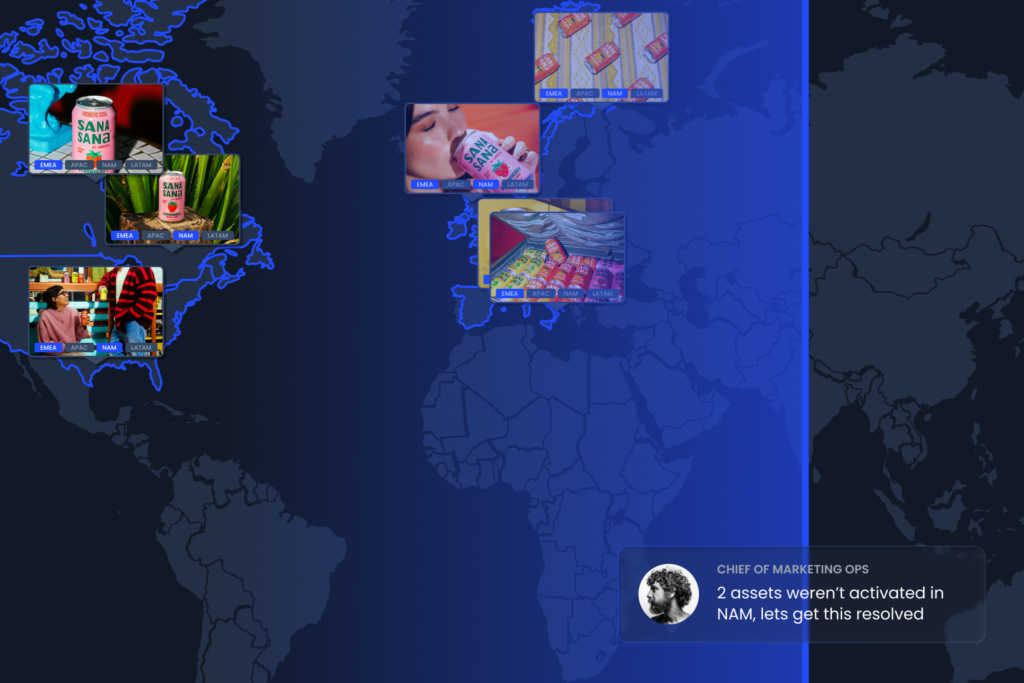
Medialake connects to your existing DAM, ad platforms and social channels, then works backwards from the live channels rather than forwards from the library. It identifies what is actually running across paid, organic, retail partner and influencer content in every market, including the channels that carry no media API and therefore never appear in agency reporting at all.
Each asset it finds is fingerprinted back to the master it derived from, using the visual and audio signature of the file rather than its filename, so the fifteen-second Polish cutdown with local voiceover and a different end card still resolves to the sixty-second original. That one capability is what makes utilisation measurable in an organisation where markets adapt everything they are sent. Every asset then carries its channel, market, flight dates and parent record, which is the difference between knowing something was used and knowing something you can act on.
Reporting runs at asset level rather than campaign level, covering utilisation across the library, penetration for each individual asset, and the list that tends to change budget conversations: the masters that were briefed, produced, approved, paid for and never ran anywhere.
It is not a DAM, and it does not store your files, hold your versions or replace anything you already own. That is why scoping takes two to three days and deployment one to two weeks, rather than the multi-month timeline of a system that has to become your source of truth first.
The first report is usually uncomfortable. Utilisation comes back lower than anyone in the room expected, and the variance between markets is wider than the average suggests, which is rather the point of running it.
Frequently asked questions
Isn’t download data good enough as a proxy? No. Downloads over-count assets pulled and never used, and under-count assets forwarded on and used widely. The error runs in both directions, so it does not even fail consistently.
Can I do this from our media agency’s reporting? Only for the channels they buy, and only at the level of detail they choose to report. It will not cover organic, retail partner or influencer activity.
How is this different from creative performance analytics? Performance analytics tells you how well the creative that ran performed. Utilisation tracking tells you what ran at all, including the assets that never made it to a channel and therefore have no performance data to analyse.
Will this work if our assets are edited by local markets? Only with content fingerprinting. Filename and metadata matching fails on recut and reversioned assets, which in most enterprise brands is nearly all of them.
How long does implementation take? It depends on whether the tool has to become your source of truth or can sit over the systems you already have. Platforms that replace something take months. Medialake scopes in two to three days and deploys in one to two weeks, because it reads from your existing DAM and channels rather than asking you to migrate into it.
What is the first thing to do? Run the manual audit above on one campaign across five markets. It takes a couple of days and tells you whether you have a problem worth automating.

